Peer Discovery, Membership, and Gossip
Questi contenuti non sono ancora disponibili nella tua lingua.
Numax combines endpoint discovery, SWIM/Lifeguard membership and K-fanout gossip to replicate CRDT operations. Periodic anti-entropy repairs missed updates using retained operations or a bounded CRDT state baseline.
Peer lifecycle
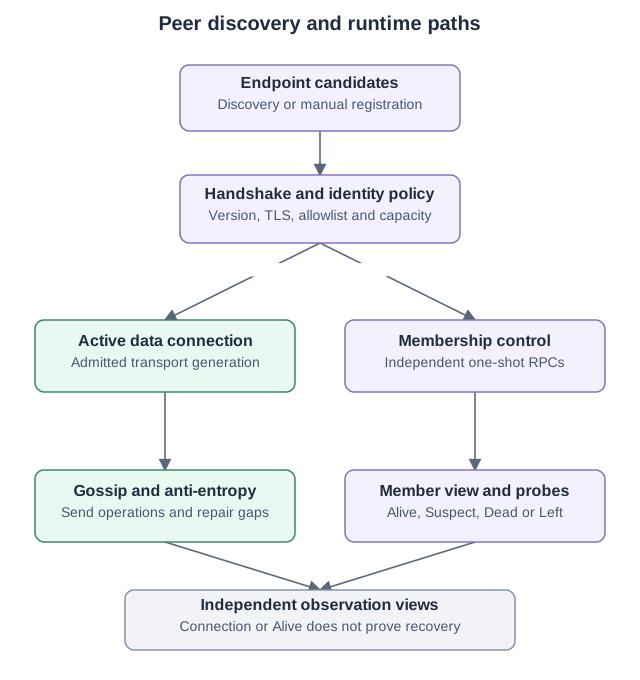
| Stage | What the node knows |
|---|---|
| Candidate | A discovery source or manual registration supplied an endpoint. |
| Admitted connection | The endpoint passed the configured handshake and identity policy. |
| Member | The control service admitted owner metadata and tracks a membership version and state. |
| Recovery | The replica tracks received operation positions and requests missing history or state. |
A connection can remain active after its discovery contribution disappears.
Membership can include nodes without a persistent data connection. Neither
Alive, an active connection nor local readiness establishes data convergence.
The Gossip Protocol introduces the message flow. The Discovery Provider Contract defines snapshot consistency, candidate ownership and provider lifecycle.
Discovery and admission
Static configuration, bootstrap, mDNS, DNS-SRV and file providers contribute to
one bounded candidate registry. Manual registrations add a separate persisted
manual contribution. The coordinator canonicalizes endpoints, deduplicates
across sources and retains their provenance. Removing one source does not remove
another source’s contribution to the same endpoint.
The registry drives initial dialing and reconnect. Every dial still passes protocol-version, identity, allowlist and connection-capacity checks. Secure TLS binds the immediate peer’s identity to its certificate; plaintext and insecure TLS retain unverified identities. An advertised endpoint or relayed record is not identity proof.
Startup succeeds when local services and their loops are ready, including when discovery is empty. It does not wait for a remote handshake or replica recovery. Failed startup can be retried after generation cleanup. Explicit shutdown is terminal and stops new manual registrations.
Membership and failure detection
Membership control uses bounded, one-shot TCP/TLS exchanges on the peer listener, separate from the data writer and data event queue. Data backpressure therefore does not hold the control writer. CPU, network capacity and executor scheduling are still shared resources.
Identity and ordering
Each member has a NodeId, durable startup epoch, self-issued
incarnation and state. Compare epoch first, incarnation second.
- Startup increments and flushes the epoch before publishing
Alive. - Self-refutation advances the incarnation and publishes a newer
Alive. - For the same pair, evidence takes precedence
Dead > Suspect > Alive. - Owner-issued
Leftcloses the epoch. Rejoin requires a newer durable epoch. - Old sessions, stale pairs and superseded timers cannot complete newer work.
Membership epochs are separate from CRDT replication generations and sequences. The membership metadata format stores identity binding and terminal rejection floors. Live sessions, timers and probe attempts are not restored from disk; fresh admission is required.
States and probes

| Event | Result |
|---|---|
| Normal admission with valid owner metadata | Establish Alive for that version. |
| A dispatched direct/indirect probe fails | Enter Suspect and start a guarded suspicion deadline. |
| A distinct authorized reporter confirms suspicion | Shorten the original deadline; duplicate reports do not extend it. |
The owner supplies a newer Alive in an open epoch | Refute the older suspicion or death. |
| A still-current suspicion expires | Persist and flush the rejection floor before publishing Dead. |
| A valid owner leave is accepted | Close the epoch; persist before publishing Left. |
An ACK establishes reachability for its correlated attempt. It does not override
same-version suspicion or death, or confirm CRDT receipt. Dead is a local
failure judgment; partitioned nodes can disagree.
Lifeguard local health makes a slow observer more cautious. With health h,
probe period and timeout scale by h + 1. Successful probes reduce health;
failed attempts, missing expected helper NACKs and self-refutation increase it
within a fixed bound. Unsent work or local dispatch failure is local degradation,
not evidence of remote failure. A locally missed scheduling interval over
100 ms cancels active attempts rather than treating that delay as a peer fault.
Suspicion starts from its first observation. Distinct additional reporters shorten its duration logarithmically between the maximum and minimum bounds. The effective confirmation threshold is frozen at creation and limited to eligible reporters. If it is zero, the minimum duration applies. Buddy notifications prioritize telling a suspected owner so it can refute.
| Runtime parameter | Value |
|---|---|
| Base probe period / direct timeout | 2 s / 500 ms |
| Active probe attempts / helpers | 1 / 3 |
| Suspicion minimum / maximum | 5 s / 15 s |
| Additional confirmation threshold | 3, clamped to eligible reporters |
| Maximum local health | 8 |
| Remote member/session capacity | 4,096 |
| Outgoing control jobs / payload limit | 8 / 16 KiB |
| Reconciliation page / minimum start spacing | 4 records / 250 ms |
| Recovery contact spacing / per-endpoint backoff | one per 25 ms tick / 1–30 s |
| Recovery wake-up minimum spacing | 5 s |
| Terminal storage queue | 64 actions plus one active worker |
Besides the reconciliation round-robin, a recovery lane contacts endpoints of
members held Suspect or Dead (never Left) and hints for unknown members.
It shares the reconciliation job limit, and each endpoint backs off from 1 s to
30 s, so a genuinely dead member costs at most one exchange per endpoint per
30 s in steady state. A reply from such an endpoint, or a local self-refutation,
makes every recovery contact due again at most once per wake-up spacing, so a
healed partition is contacted promptly and a refuted Alive reaches members
that may still hold the owner dead. These contacts carry no extra authority.
These are internal runtime settings, not CLI options or a universal detection
latency guarantee. Storage failure fences terminal publication and is exposed
through service errors. Membership shutdown allows two seconds for leave
dissemination and five seconds for adapter completion. If that budget expires
before the terminal leave is durably confirmed, shutdown returns the typed
ShutdownPending::DurabilityUnconfirmed error and retains the adapter, discovery
and transport. A confirmation first observed after the call’s deadline returns
ShutdownPending::DurableLeaveConfirmedLate. Retrying SyncManager::shutdown
resumes the same outcome instead of repeating the leave commit or reporting
premature success. Callers can downcast the error; they must distinguish it
from definitive storage errors, which remain errors on retry. Node data loops
are joined before the leave is written. Dropping the manager is the terminal abort: an
in-flight filesystem operation may still finish, but cannot publish through the
stopped adapter.
Control authority
| Input | Authority |
|---|---|
Direct owner Alive or refutation | Must match the admitted immediate identity, current session and ordering rules. |
Direct owner Left | Must match the owner’s current pair; closes that epoch. |
Suspect / Dead evidence | Comes from an admitted reporter for a known subject pair. |
Forwarded Alive | Supplies an endpoint hint; the owner must be revalidated directly. |
| Forwarded suspicion | Counts only when its attributed reporter is the immediate admitted sender. |
Relayed Left | May close an already-known exact subject pair under the cooperative relay rule. |
| Probe ACK/NACK | Must match an active request, target version and captured target/helper session. |
An indirect helper probes a known target without recursive indirect requests. A NACK is helper feedback, not a death verdict. Relays authenticate the immediate sender, not the claimed origin of another node’s update. This is a cooperative crash-fault model, without transferable owner signatures or Byzantine resistance.
Mutual suspicion or death must not prevent an owner from learning its own
failure judgment. For a known exact owner pair in an open epoch, a rejected
Alive request may receive only that owner’s Suspect/Dead verdict. A
correlated reply from an equally rejected owner may trigger only self-refutation:
it cannot authorize reports about other members, supply hints or pagination,
relay probes, or complete a probe successfully. This applies to restored durable
death floors too, without creating an admitted session. Symmetrically, a
rejected request from such an owner may make the receiver refute only the
sender’s own Suspect/Dead verdict about the receiver; it changes nothing else.
Superseded pairs and
epochs closed by Left (including a pending leave) cannot use this path.
Normal admission still requires a newer owner incarnation; an old Alive
never overrides same-version evidence. Terminal publication still follows a
covering flush.
Local acceptance and durability
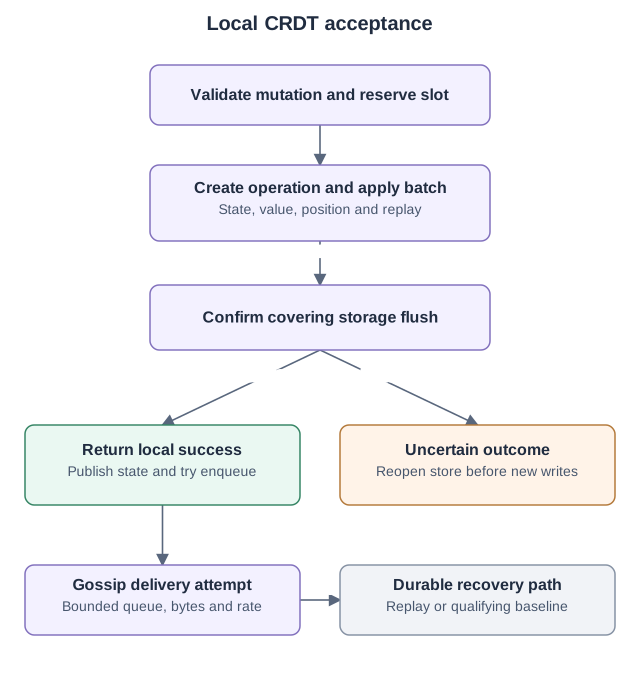
A local CRDT mutation creates its identity before persistence and commits these records in one atomic storage batch:
- CRDT internal state and materialized value;
- operation UUID and replication position;
- seen-operation metadata, receipt coverage and replay record.
The caller receives success only after a covering storage flush. This applies to GCounter, PNCounter, LWW-Register, LWW-Map, ORSet and RGA. A successful local write can precede every peer connection.
Acknowledgement semantics
| Result | Guarantee |
|---|---|
| Atomic batch applied | Its records were accepted together; no covering flush is implied. |
| Local mutation succeeded | Its acceptance batch has a confirmed covering flush. |
| Transport send succeeded | The local stream write completed; remote apply or storage durability is not confirmed. |
| Remote operation applied | A nonempty batch atomically persists state and receipt metadata and awaits a covering flush before publication and forwarding (experimental backpressure). |
| Baseline installed successfully | The complete replacement and receipt cut were atomically installed and flushed. |
The replication path does not wait for a replica count, quorum or per-operation
remote durability ACK. The legacy PushOpsAck wire variant is not used to prove
receipt or durability. Local acceptance and remote replication are separate.
Retry contract
A rejected batch leaves the mutation unpublished. A failed flush, lost response or interruption after persistence can leave an uncertain outcome: the operation may survive even though the caller did not receive success. A failed flush fences subsequent writes until the datastore is reopened.
Guest mutation calls do not accept a caller-supplied idempotency key. Repeating a logical mutation can therefore create a second operation. Retry delivery from retained history; do not repeat the mutation just to resend it. ORSet removal with no observed tags is a successful no-op without a new operation. RGA insert uses its operation ID as the element ID and validates guest output before persistence. SDK mutation wrappers do not automatically retry internal errors; the RGA buffer-size retry is safe only because it precedes persistence.
Failure model
The local durability contract covers process termination with an intact, reopenable datastore. Before the batch the operation is absent; between batch and flush the complete batch may or may not survive; after confirmed flush its records survive under this model. This is not a power-loss, OS-reboot or storage-device-loss guarantee. Losing the only surviving durable source cannot be repaired by gossip.
Operation identity and receipt coverage
The UUID OpId identifies an operation. Its replication envelope also carries
(origin, generation, sequence): generation advances durably at startup, while
the per-origin sequence remains monotonic across restarts. Startup rejects a
store bound to another local NodeId.
A receiver persists contiguous coverage and sparse positions in the same batch as the CRDT change. Replays at covered positions have no second effect and are not forwarded again, even after the bounded UUID cache or replay log evicts those entries. Invalid positions and conflicts with retained identity/position metadata are rejected. The largest observed UUID or advertised sequence is not a completeness frontier.
| Receipt-tracking bound | Value |
|---|---|
| Origins | 1,024 |
| Sparse positions per origin / total | 256 / 8,192 |
| Tracking metadata | 4 MiB |
| Maximum accepted forward sequence gap | 65,536 |
Exceeding these bounds does not apply or acknowledge the rejected operation as received. The repair path can still request earlier missing ranges.
Gossip and backpressure
New local operations and newly persisted remote operations enter separate volatile delivery queues. Forwarding preserves the original identity and position, excludes the immediate sender and suppresses duplicate forwarding.
Fanout
The fanout uses a local membership estimate:
N = unique identities in {local node, Alive/Suspect members, active data peers}K = min(ceil(log2(N)) + c, gossip_max_fanout, eligible connections)The default c is 3 and gossip_max_fanout is 64. No eligible connection means
K is zero. Each node derives its recipient order from its identity and
connection addresses, then rotates through it. The estimate is not a cluster
census; the formula alone does not establish connectivity or convergence.
Bounded neighbors and recovery contacts
Active data connections, including inbound sessions, remain bounded by
max_peers. The reconnect pool combines discovery with up to 64 canonical
membership recovery endpoints per window. It never promotes an inbound socket’s
ephemeral source port into a recovery contact.
Each turn advances dial priority and attempts at most eight dials with existing
per-endpoint backoff. Every 30 seconds the recovery window rotates. With full
slots and an eligible alternative, at most one managed neighbor is replaced in
that interval. Existing connections to the same membership identity satisfy the
contact without a redundant reverse dial. When a member returns to Alive at a
newer version, its endpoint’s backoff restarts from the initial delay at most
once per rotation interval, so a healed partition is redialed promptly.
Dead contacts remain eligible so healed partitions can reconnect. Left
contacts are excluded until fresh owner admission supersedes them. Discovery
withdrawal suppresses new attempts at that endpoint, including through retained
membership, but leaves an admitted session open. A later discovery addition can
restore eligibility.
The withdrawal cache retains at most 4,096 endpoints. Exhaustion disables membership-only data recovery until restart, with an error metric and warning; current discovery candidates remain usable. Contacts and withdrawals are runtime state. After restart, discovery and persisted manual candidates bootstrap the member view again.
Rate adaptation
Local gossip and forwarding share a per-connection byte bucket. Pacing uses queue pressure, smoothed direct-control round trips and local writer service time as distinct signals. Connection setup, TLS setup, indirect replies and stale samples do not become RTT measurements.
Congestion halves the rate within its configured floor. Healthy demand restores it additively within its ceiling. Decisions are limited to one per second; hysteresis avoids reacting repeatedly to one RTT spike. Queue pressure alone does not cause a slowdown. Unused credit is capped by the burst allowance; a validated frame larger than the burst may overdraw once, with debt bounded by that frame.
Resource budgets
| Boundary | Limit |
|---|---|
| Local / forwarding queue | Each: max(1, queued_ops_limit) items and 8 MiB accounted payload |
| Batch construction | At most 1,024 items and min(max_message_size, 8 MiB) - 256 bytes of conservatively sized payload |
| Carry-over | At most one item per delivery loop, separately from its queue and batch |
| Local / forwarding turn | Each: at most 64 prepared attempts and 16 MiB framed bytes |
| Recovery output | Node-wide: 64 frames and 16 MiB per one-second window, independent of gossip |
| Recovery response construction | At most 64 summary/range/baseline requests per one-second window |
| Writer acquisition and transmission | min(socket_timeout, 250 ms) together |
Queue credits return on dequeue or drop. These are payload and work limits, not total process-memory limits: in-flight batches, transport decoding, CRDT registries and storage caches have separate responsibilities. A failed or partial write closes that connection generation; its reader owns cleanup without making the sender wait on the data event queue.
Coalescing adds deterministic jitter between 0 and 2 ms, seeded with local and
operation identity. Repair skips missed ticks and shortens its configured period
by up to min(interval / 8, 1 s). Reconnect adds up to one eighth of its wait,
capped by the configured maximum.
A full queue, exhausted pacing/budget or failed send discards only the volatile attempt. It does not delete the accepted state or its recovery metadata. Periodic repair uses the retained history and baseline contract below; no unbounded retry queue is created.
Anti-entropy and recovery
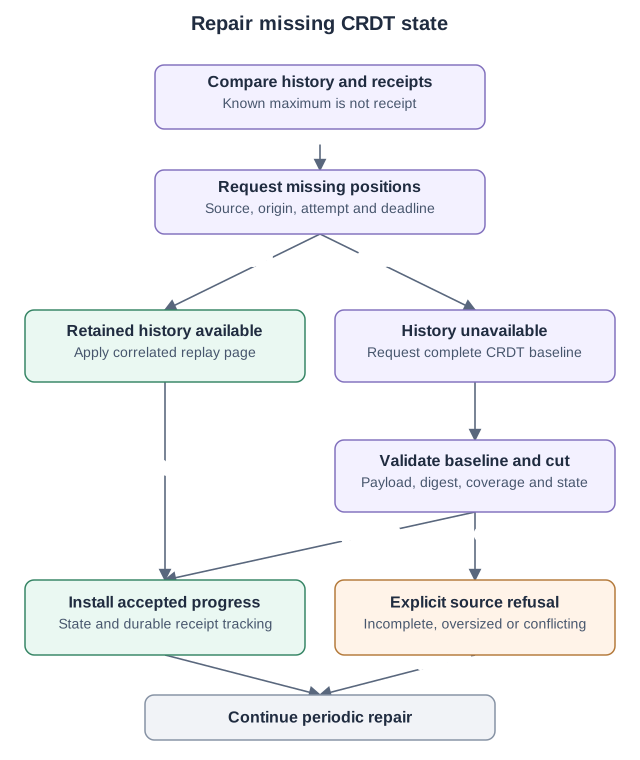
Anti-entropy uses all active data connections, including inbound sessions and connections no longer present in discovery. Its default interval is 30 seconds. It exchanges per-origin summaries, compares advertised history with durable receipt coverage and requests missing ranges.
Each periodic turn starts a bounded catch-up session that walks one peer’s
summary pages back to back, even when an aligned first page reveals no gap.
A session also starts when a data session connects and when a membership record
returns to Alive at a newer version, because a partition can heal without the
transport ever dropping that session. Starting a periodic walk does not reset
an outstanding summary deadline, cursor or rewalk backoff. A walk
that found gaps is repeated after 2, 4, 8 and 16 seconds at most, then the
periodic cadence takes over; a walk without gaps ends the session. A summary
request is considered unanswered after min(socket timeout, 2 s) and is
retried by the session; range and baseline requests keep the socket timeout.
An origin already requested from another peer within the last 2 seconds is not
requested again, so a reconnecting cluster does not ask every peer for the
same history while a lost request is still hedged by later walks.
Retention window
Each node retains the last max(1, op_log_limit) operations across all origins
in insertion order, default 10,000. This is a count window, not a time guarantee.
New local writes, imported operations and a smaller restart limit can evict
history. Receipt coverage survives eviction.
Replay requires a reachable admitted source that actually retains the requested
positions. An Unavailable response describes one source and range; another
source may still repair it. New nodes also need replay or a valid baseline before
they have complete historical state.
Bounded state transfer
When history is unavailable or a required legacy baseline is missing, Numax requests baseline format 1. The source exports a complete cut of all six CRDT families and origin coverage, with a covering flush and BLAKE3 digest. The payload uses JSON independently of the negotiated outer codec. It includes full CRDT state, including LWW winners, ORSet tags and RGA tombstones; it excludes ordinary KV data, modules and transport identity.
| Baseline bound | Value |
|---|---|
| Encoded payload | 1 MiB |
| State records / key length | 4,096 / 4,096 bytes |
| Origins | 1,024 |
| RGA materialization | 4,096 elements, depth 128 |
The source must have complete coverage without sparse receipts, missing legacy state or an unconfirmed baseline. The receiver accepts only a dominating complete cut: it covers every already-applied position and legacy baseline, includes existing keys, dominates their internal CRDT state, and preserves the local allocator. Concurrent local writes or incomparable cuts can cause refusal. This is not arbitrary divergent-state reconciliation.
Installation replaces state, materialized values and coverage atomically, then flushes. Interrupted frames install nothing. A rejected batch publishes nothing. An uncertain flush may leave the complete installed batch; a persisted marker prevents confirmed baseline completion or export until reopening and a covering restart flush. Later replay starts after the imported cut; known positions beyond it remain pending.
Recovery outcomes
| Outcome | Meaning |
|---|---|
| Missing positions | Known operations remain to be received. |
| Missing legacy baseline | New sequence coverage does not cover historical unsequenced state. |
| Unconfirmed baseline | Installation lacks a confirmed covering flush. |
UnsupportedVersion | The requested baseline format is unsupported. |
SourceIncomplete | This source cannot export a complete cut. |
BudgetExceeded | The baseline or its encoded frame exceeds an applicable limit. |
CoverageConflict | The offered cut cannot safely replace the receiver’s applied state. |
InvalidState | Baseline validation failed. |
Refusals are correlated to the request and its captured coverage revision. A stale refusal cannot describe a later recovery state. Storage failures retain their operational error; they are not converted into a misleading baseline refusal. Periodic repair continues and another source may succeed.
No known gap is a statement about discovered history, not proof that every cluster operation has been discovered. If no surviving source can supply the required history or a qualifying baseline, recovery fails explicitly under these bounds. Larger snapshots and incomparable-cut merging remain outside the implemented contract.
Management and observation
Use POST /api/v1/peers to register a persistent manual candidate. Acceptance confirms storage and coordinator publication; connection, authentication and replica recovery follow through their normal paths.
GET /api/v1/peers lists active peers. Its optional views expose candidates,
connections, membership and per-origin recovery separately. The
Management API guide
describes fields, pagination and uncertain outcomes. The
Observability guide
provides bounded-label probe, queue, retry, fanout and gap metrics.
Compatibility and limits
Protocol 9 requires an exact version match. A v0.1.5 peer using protocol 5 is
rejected before admission or CRDT exchange. JSON and Bincode (wincode) obey the
same compatibility policy; preserving legacy public codec bytes does not make
older peers compatible.
Historical stores require the explicit schema migration. Legacy UUID-only replay is retained locally but is not automatically replayed as sequenced history. Its baseline requirement survives new writes and restart. See Wire Versioning for deployment rules.
Release-wide loss/partition, rolling-restart and sustained detector criteria remain in the roadmap. They are separate from these runtime contracts. Test procedures and recorded experiments are maintained in the sync manager test guide.