Gossip Protocol
Numax spreads CRDT operations through a bounded selection of peers. Each receiver persists a new operation before forwarding it. Periodic anti-entropy repairs updates missed because of disconnection, backpressure or partitions.
From endpoint to replica
A node first needs an endpoint to try. Static configuration, bootstrap, mDNS, DNS-SRV and file discovery can supply candidates; the Management API can also add a persistent manual candidate.
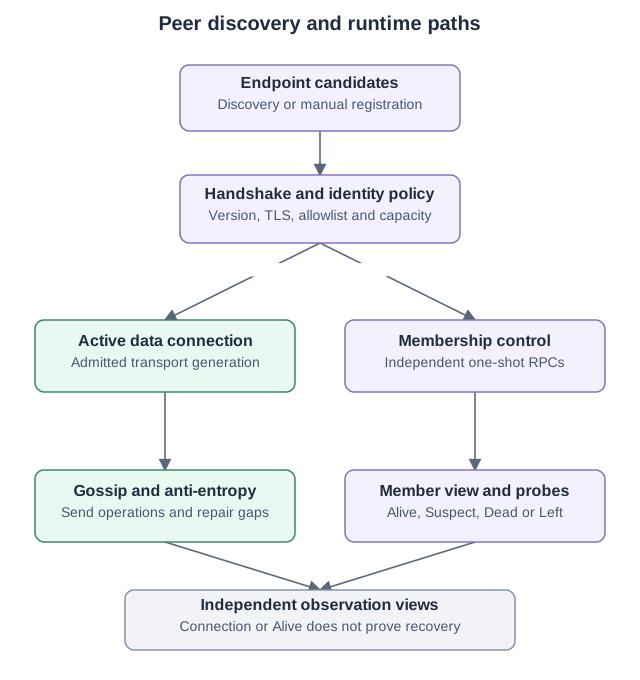
These stages answer different questions:
| Observation | Meaning |
|---|---|
| Candidate | An address is available for dialing. |
| Active connection | The peer passed the configured transport admission policy. |
Membership Alive | The control service has a current member view. |
| Recovery progress | The replica knows which discovered operation positions it has received. |
Discovery does not authenticate an endpoint. Secure TLS binds the immediate
peer’s NodeId to its certificate; allowlists can restrict admission. Plaintext
and insecure TLS identities remain unverified. The node can start with no
candidates, and local readiness does not wait for cluster convergence.
Gossip is the fast path
A local CRDT mutation gets a UUID OpId and a per-origin replication position.
State, materialized value and replay metadata are committed together, then
flushed before local success. The operation becomes eligible for delivery to
selected active connections.
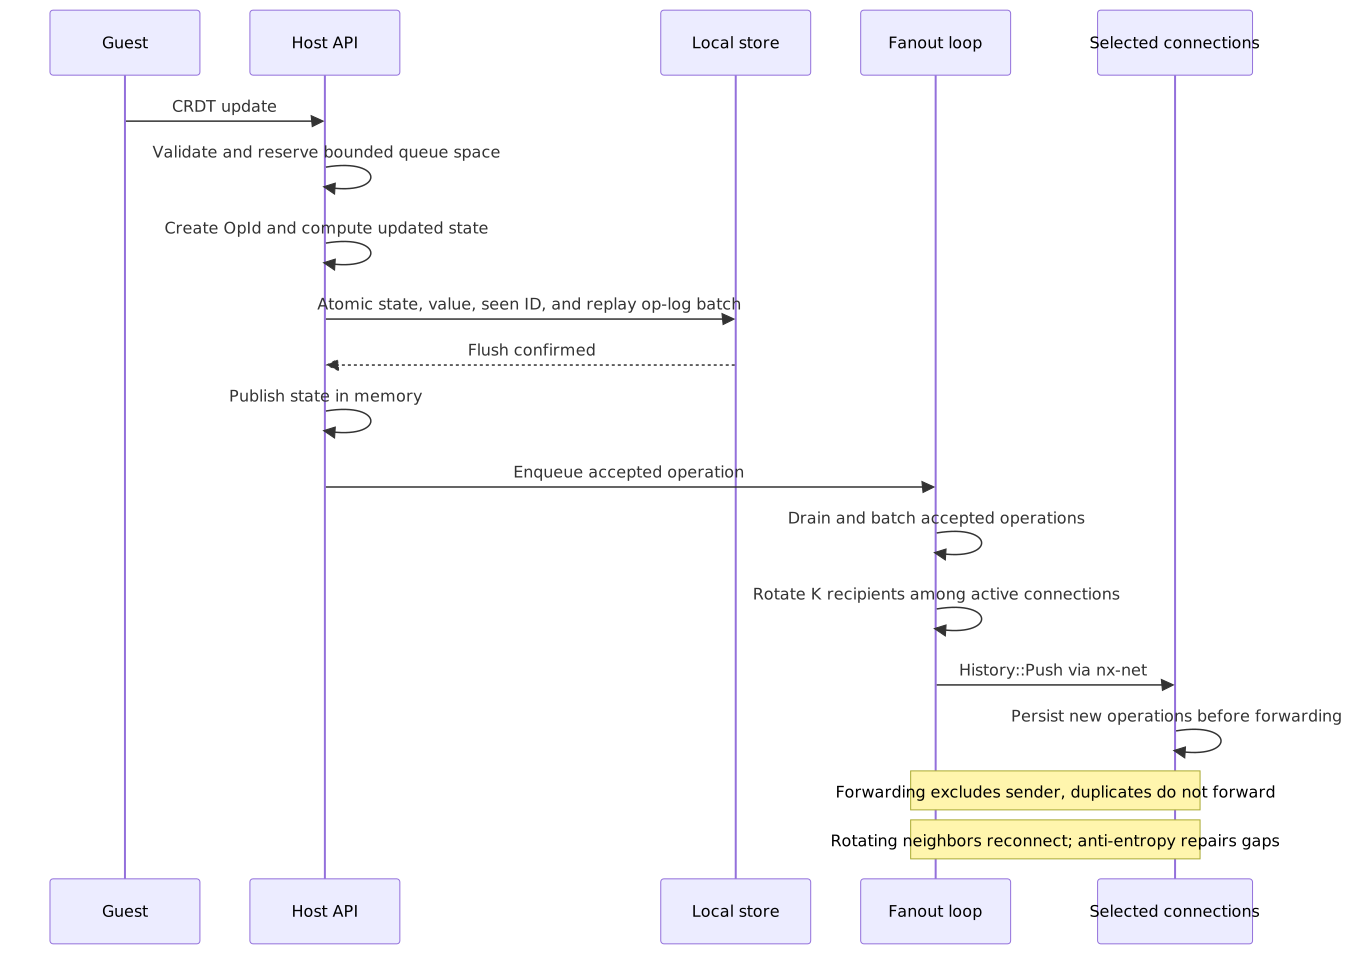
Receivers persist newly accepted operations before forwarding them with their original identity and position. Durable receipt tracking prevents a delayed duplicate from applying or forwarding again after the UUID cache expires. Ordinary KV writes and CRDT writes have separate paths; not every KV write is replicated.
A successful send confirms a local stream write. It does not confirm remote application or storage durability. Local CRDT success does not wait for an ACK, replica count or quorum. See the acceptance contract.
Fanout and neighbors
For each batch, the sender chooses at most K eligible active connections:
N = unique identities across the local node, Alive/Suspect members and active peersK = min(ceil(log2(N)) + c, gossip_max_fanout, eligible connections)The default c is 3; the maximum fanout is 64. N is a local estimate rather than
an exact cluster census. With no eligible connection, K is zero. Each node
rotates through a recipient order derived from its identity and connection
addresses; forwarding excludes the immediate sender.
Connection topology has a separate policy. Active connections are bounded by
max_peers, and the reconnect pool includes a rotating window of membership
recovery contacts. Dead contacts remain useful after a partition; Left
contacts are excluded until fresh owner admission. With full slots, the runtime
can replace one managed neighbor per 30-second interval to try an alternative.
Discovery removal stops new attempts at the endpoint but leaves an admitted connection open. Anti-entropy continues over that connection. The topology contract defines contact, withdrawal and rotation limits.
Backpressure and pacing
Local and forwarding queues have item and byte limits. Batch construction, transport writes and recovery work also have explicit budgets. A rejected or failed send attempt leaves the accepted operation’s durable state and recovery metadata intact.
Local gossip and forwarding share an adaptive per-connection byte bucket. Smoothed direct-control RTT and writer service time provide congestion feedback; queue demand supports gradual recovery of the rate. Connection setup and TLS setup are excluded from RTT samples. Jitter spreads coalescing, polling and reconnect work over time.
Defaults exposed under [limits] include:
| Setting | Default |
|---|---|
max_peers | 64 |
queued_ops_limit | 10,000 per delivery queue |
gossip_fanout_constant / gossip_max_fanout | 3 / 64 |
gossip_min_bytes_per_second | 65,536 per peer |
gossip_max_bytes_per_second | 4,194,304 per peer |
gossip_burst_bytes | 256KiB |
anti_entropy_interval | 30s |
op_log_limit | 10,000 operations across origins |
See Configuration for supported settings and resource budgets for internal limits. These budgets do not constitute a total process-memory cap.
Anti-entropy is the repair path
Anti-entropy exchanges bounded per-origin history summaries over active data connections. It compares advertised history with durable contiguous coverage and sparse receipts, then requests missing ranges. An observed maximum alone cannot establish that every preceding operation was received.
Replies are correlated with a source, origin, request ID, interval and deadline. Missed or stale replies do not complete newer requests. The loop uses all active connections, including inbound peers and peers removed from discovery.
The replay log retains a count of operations, not a guaranteed duration. New writes can evict history needed by an offline peer. If replay is unavailable, Numax attempts a complete, versioned CRDT baseline within a 1 MiB payload budget. It includes all six families and their tombstones, together with receipt coverage.
The baseline must cover the receiver’s applied history and dominate its existing state. Incomplete sources, oversized state and incomparable cuts can therefore refuse recovery explicitly. Another source may still succeed. This mechanism does not provide arbitrary snapshot merging or unrestricted recovery after history expires.
The recovery contract
describes retention, baseline limits and failure outcomes. A connected or
Alive node can still have missing state; zero known gaps is not a certificate
of global convergence.
Membership and reconnection
SWIM/Lifeguard membership uses independent one-shot control connections for probes and member exchange. Suspicion can be refuted by a newer owner update; local health slows a degraded detector instead of treating every local delay as a remote fault. Epochs and terminal rejection floors preserve ordering across restart and leave/rejoin.
Endpoint reconnect health is separate from this detector. Its Healthy,
Suspect and Dead states describe connection attempts and their failure
threshold. Reconnect uses exponential backoff, defaulting to 500 ms initially
and 30 seconds maximum, with jitter. Three consecutive failures reach the
endpoint-health Dead state; this does not discard a membership recovery contact.
Operate a node
- Configure discovery to obtain initial contacts.
- Add manual candidates at runtime.
- Inspect peer views to distinguish candidates, connections, membership and recovery.
- Monitor metrics for probes, queue pressure, retries and gaps.
- Read the design contracts for ordering, durability and recovery boundaries.